The Evolution of Captcha Obstacles in the AI Age
Advancement of Processing Power in 2026 Search Optimization
The technical requirements for information analysis have shifted substantially as we advance through 2026. Seo is no longer a task restricted to simple keyword tracking or fundamental metadata audits. Instead, the focus has actually moved towards enormous data consumption and real-time analysis of countless data points. To keep performance, software should now connect with hardware in such a way that goes beyond standard CPU processing. Standard serial execution has a hard time to keep pace with the large volume of information being created and indexed every hour.
Hardware acceleration has actually emerged as a need for companies handling large-scale search data. By shifting particular computational tasks from a general-purpose Central Processing System (CPU) to specialized hardware like Graphics Processing Units (GPUs) or Tensor Processing Systems (TPUs), software application can process countless operations all at once. This shift is particularly apparent in the method contemporary crawlers and analysis tools deal with natural language processing (NLP) In 2026, the demand for Michael Swart Analysis has actually increased as groups search for methods to minimize the time it requires to parse semantic relationships in between billions of web pages.
The Function of Multi-Core Architectures in Data Parsing
Modern servers in 2026 regularly feature processors with 128 cores or more as a standard setup. Having high core counts is just half of the service. Software application should be composed to support multithreading, enabling it to divide complicated jobs into smaller sized pieces that run in parallel. When a spider hits a big site, a single-threaded application would process pages one by one, creating a massive queue that might take days to clear. A multithreaded technique permits the software to fetch, parse, and examine numerous pages at the same time.
Effectiveness in these tasks depends greatly on memory bandwidth. Even the fastest processor can be throttled if the system can stagnate information from the RAM to the CPU quickly enough. With the adoption of DDR6 memory in 2026, information transfer rates have reached brand-new heights, allowing multithreaded applications to operate without the data traffic jams that prevailed in previous years. This enables deeper analysis, such as recognizing complex internal linking structures across enormous business websites in minutes instead of hours.

GPU Offloading for Large Language Design Analysis
Large Language Models (LLMs) have ended up being a staple for assessing content quality and significance. Running these designs on a basic CPU is infamously slow and energy-intensive. Hardware velocity through GPUs enables the parallel processing of the matrix reproductions that power these designs. When an SEO tool analyzes the topical authority of a site, it uses these accelerated kernels to compare content against countless high-ranking documents in real-time.
Designers are significantly using specialized libraries to ensure their software application can communicate straight with GPU hardware. This direct interaction bypasses much of the overhead connected with the operating system, leading to significant efficiency gains. Organizations that focus on Michael Swart Blacklist Filter Methods typically discover that their capability to predict ranking shifts enhances as they can run more complicated simulations on their local hardware without depending on costly cloud-based API calls.
Optimizing Storage I/O for High-Speed Crawling
Data determination is an often ignored element of technical infrastructure. When running countless threads, the demand on the storage system is tremendous. Every thread requires to compose its results to a database or a flat file. Standard Strong State Drives (SSDs) can reach their limit when faced with the high Input/Output Operations Per Second (IOPS) required by massive scale SEO operations. In 2026, the transition to PCIe 7.0 storage user interfaces has actually provided the required throughput to manage these workloads.
Using NVMe drives with high endurance ratings is essential. These drives permit the software to maintain high compose speeds even as the disk fills. Without this hardware support, multithreaded software application would experience "I/O wait" states, where the CPU is idle because it is waiting for the storage system to finish writing data. This latency can destroy the effectiveness of a well-coded multithreaded application. Effective data storage guarantees that the insights gained from crawling are readily available for analysis immediately.
Network Infrastructure and Latency Management
Hardware acceleration likewise extends to network user interface cards (NICs) In 2026, high-end SEO servers use smart NICs that can handle packet processing and encryption offloading. This suggests the main CPU does not need to invest cycles managing the overhead of thousands of simultaneous HTTPS connections. By moving these tasks to the network hardware, the system can preserve higher connection speeds and lower latency when communicating with web servers across the world.
Low latency is important when performing real-time analysis. If a spider takes 200 milliseconds to establish a connection due to hardware overhead, that time adds up throughout millions of pages. Smart NICs minimize this overhead, permitting for a more aggressive crawling schedule without overloading the host system. This level of optimization is what separates requirement tools from professional-grade infrastructure in the present year.
Thermal Management in High-Density Compute Environments
Running high-core-count CPUs and effective GPUs at maximum capacity produces a remarkable quantity of heat. Thermal throttling is a major opponent of software performance. When a processor gets too hot, it automatically minimizes its clock speed to prevent damage, which decreases the multithreaded tasks. In 2026, liquid cooling has ended up being a common function in data centers devoted to heavy data processing. Keeping the hardware at a consistent temperature level enables the software application to run at peak efficiency for extended periods.
Facilities designers now take a look at the total thermal style power (TDP) of their setups. They guarantee that the cooling capacity goes beyond the heat output of the hardware throughout a 100% load scenario. This is particularly important for SEO tasks that may run for a number of days straight, such as a complete index revitalize for a global e-commerce platform. Stable temperatures lead to predictable processing times, which is essential for satisfying task due dates.
Setting for Hardware Performance
Software application developers are altering how they write code to much better fit 2026 hardware. Languages that provide low-level memory management and direct access to hardware directions are chosen for constructing high-performance SEO tools. Techniques such as Single Guideline, Multiple Data (SIMD) enable the software to perform the very same operation on numerous information points in a single clock cycle. This is exceptionally helpful for jobs like determining the resemblance between two different page variations or processing large batches of redirect guidelines.
Asynchronous shows is another essential element. Rather of a thread waiting on a response from a server, it can move on to another task while the hardware handles the network request in the background. This makes sure that the CPU stays active as much as possible. By combining asynchronous I/O with hardware velocity, designers can produce tools that are a number of orders of magnitude much faster than those used simply a few years ago. The objective is to lessen the "dead time" where hardware is sitting idle.
Integrating AI Accelerators into the Workflow
The rise of devoted AI accelerators has supplied a brand-new opportunity for optimization. These chips are developed particularly for the types of mathematical operations used in artificial intelligence. In the context of SEO, these accelerators can be used to classify millions of images or equate material into different languages for international analysis at a fraction of the power cost of a conventional CPU. This customized hardware makes it possible to perform jobs that were previously too costly or slow to think about.
Incorporating these accelerators requires a deep understanding of the underlying hardware architecture. Nevertheless, the outcome is an enormous boost in throughput. Analyzing the visual belief of every image on an enormous social platform becomes a feasible task when using devoted AI silicon. This enables a far more nuanced understanding of how visual content effects browse presence and user engagement.
The Impact of 400GbE Networking on Dispersed Crawling
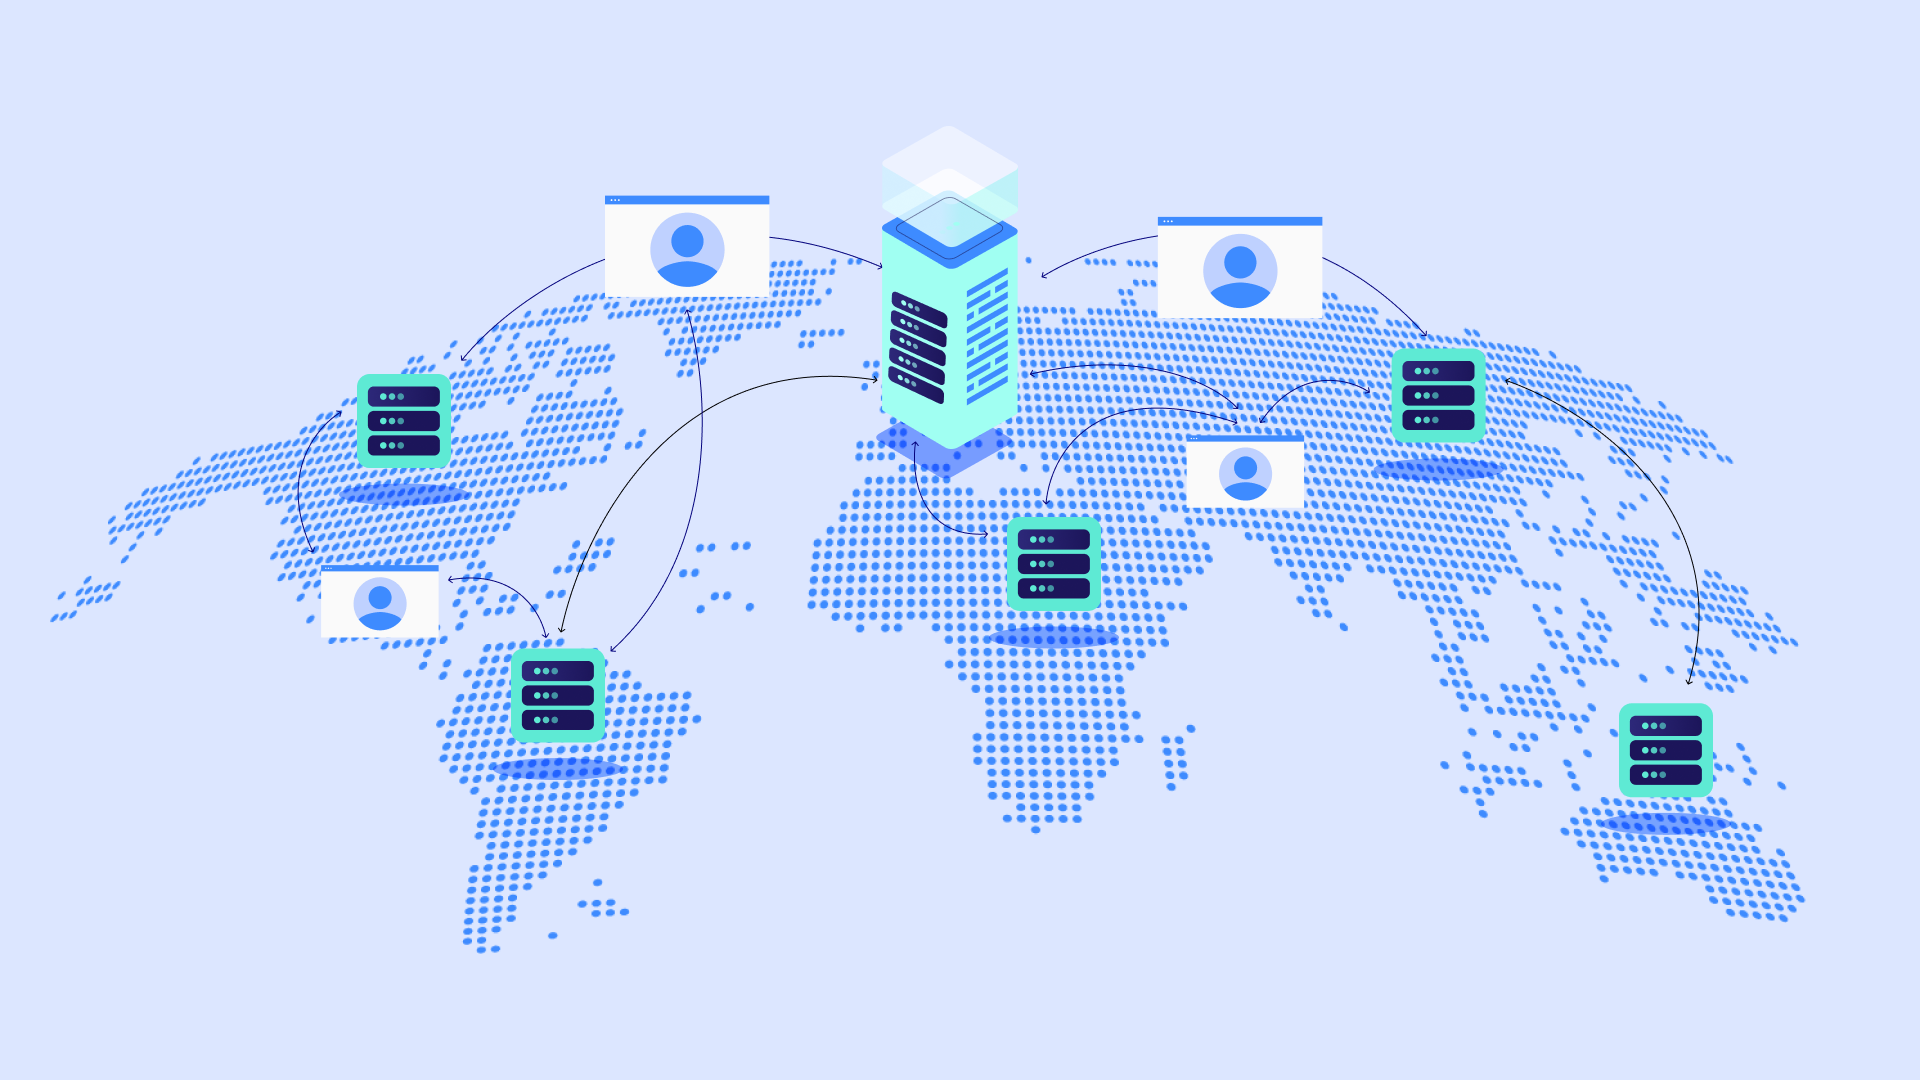
As we move through 2026, the adoption of 400 Gigabit Ethernet (400GbE) in significant data centers has actually changed the scale of distributed crawling. When a crawler is spread throughout numerous physical servers, the speed of the internal network ends up being a factor. High-speed networking allows these servers to share information practically as rapidly as if it were on a regional disk. This makes it possible for a level of coordination in between threads that was formerly difficult.
Dispersed systems can now share a single, massive hash table of gone to URLs across numerous nodes without considerable latency. This prevents redundant crawling and ensures that the entire system is working as effectively as possible. Hardware-level network optimization is the glue that holds these huge distributed systems together, enabling them to function as a single, cohesive unit. This scale of operation is now the standard for high-level information analysis in the search market.
Conclusion of Technical Considerations
The shift towards hardware velocity represents a growing of the technical side of the market. In 2026, the most effective operations are those that treat software and hardware as a single, integrated system. By enhancing for the particular capabilities of modern CPUs, GPUs, and network hardware, it is possible to attain levels of performance that were once believed to be simply theoretical. As data volumes continue to grow, the importance of this technical structure will only increase, making hardware awareness a core proficiency for any severe technical specialist.